Supervising the search process produces reliable and generalizable information-seeking agents

Nature Communications, 2026
1Department of Computer Science, University of Virginia
2National Library of Medicine, National Institutes of Health
3Department of Computer Science, University of Illinois Urbana-Champaign
4Department of Medical Oncology, Dana-Farber Cancer Institute
5Department of Surgery, University of Alabama at Birmingham
6Department of Neurology, Yale School of Medicine
*Equal Contribution, †Co-correspondence

Abstract

Large language models (LLMs) are transforming web search by shifting from document ranking to synthesizing answers, and are increasingly deployed as autonomous agentic search systems that iteratively interact with external knowledge sources. Despite this progress, building effective search agents remains challenging because high-quality intermediate search steps are difficult to generate. Previous approaches have primarily relied on outcome supervision, rewarding agents only for producing correct final answers. This often leads to reward hacking and excessive dependence on parametric memory, limiting generalization to out-of-domain tasks.

To address these limitations, we introduce RAG-Gym, a framework that shifts supervision from final answers to the search process itself. With RAG-Gym, we systematically investigate architecture design, parameter optimization, and action evaluation, identifying reasoning reflection as a critical capability for search agents.

Building on this insight, we propose Re²Search++, a process-supervised agent that achieves substantial improvements on multi-hop information-seeking benchmarks, especially in out-of-domain settings. Performance gains are driven primarily by higher-quality search queries rather than answer optimization alone, and the learned search critics transfer across models, including proprietary LLMs. These findings show that supervising the search process produces more reliable and generalizable information-seeking agents.
RAG-Gym Framework

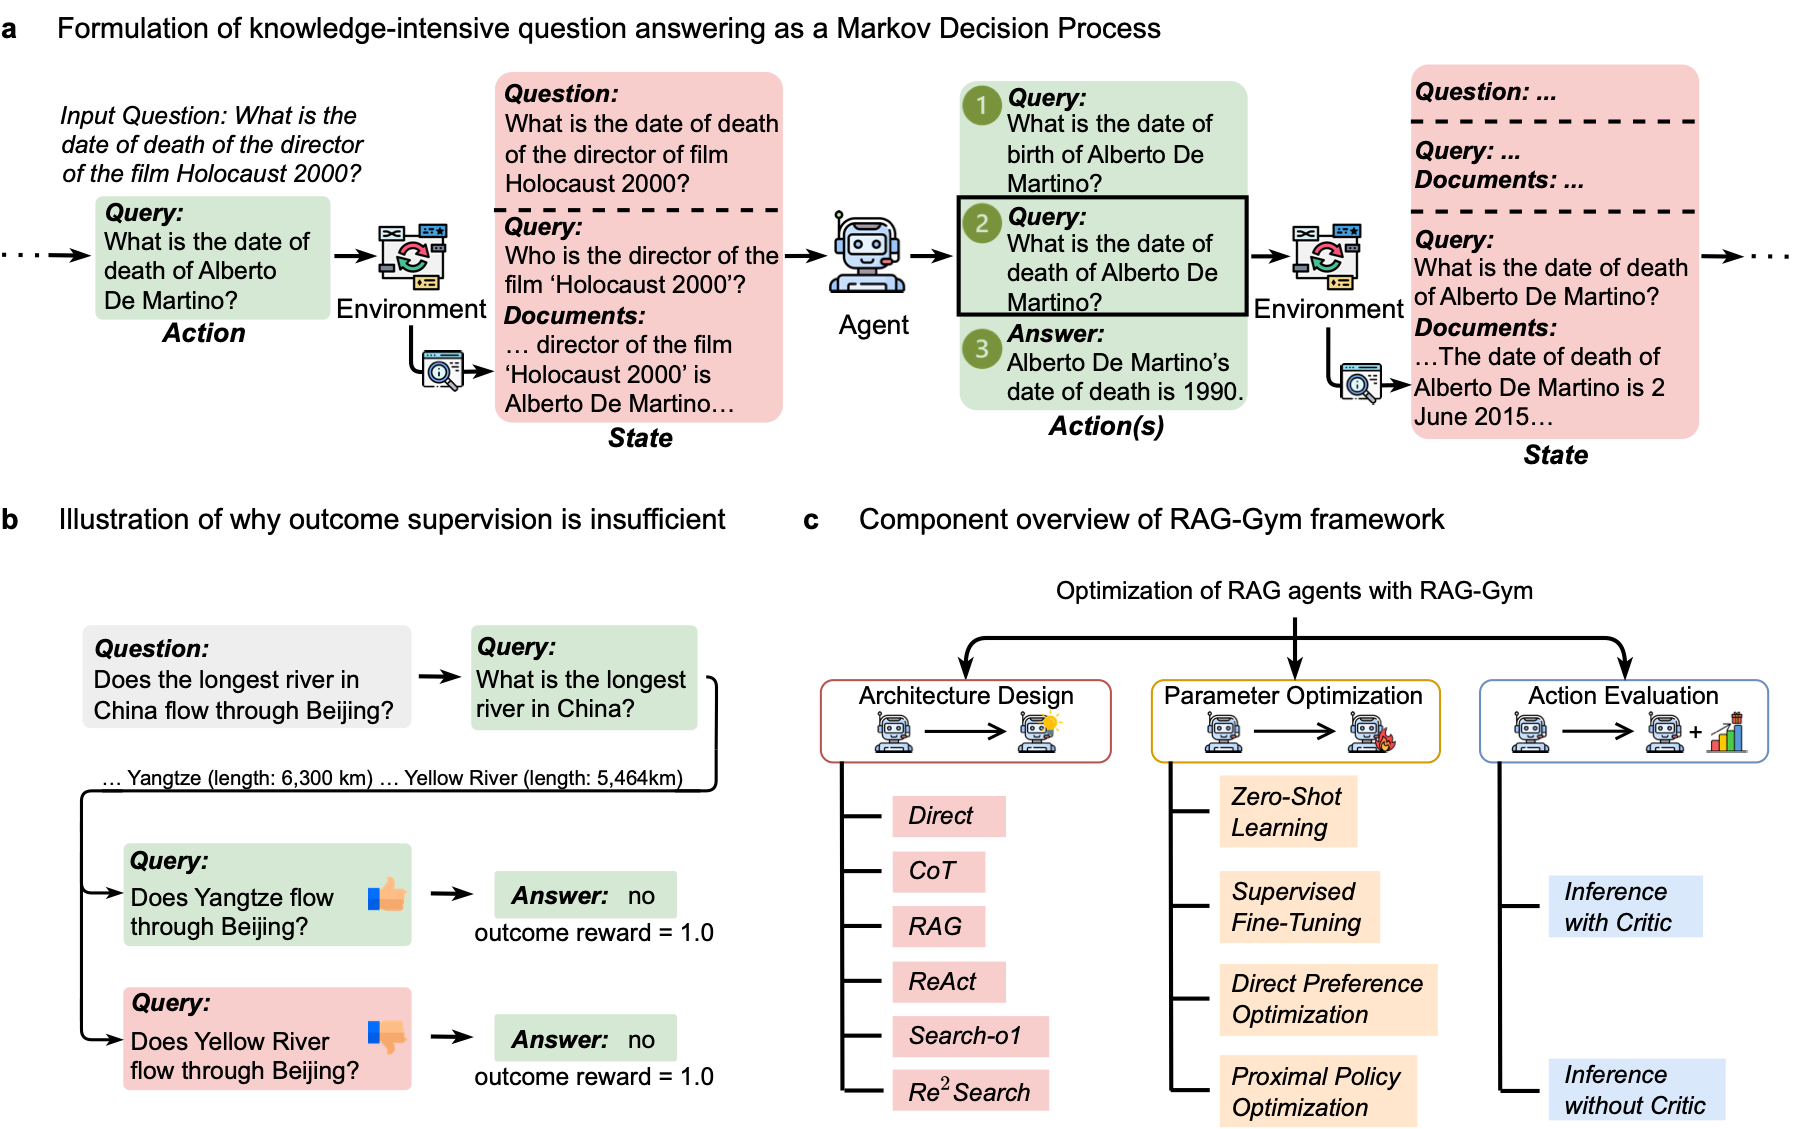
RAG-Gym formulates agentic search as a high-level Markov decision process (MDP), in which each step is a macro-action: issuing a search query or generating the final answer. This exposes intermediate search steps to direct supervision. Outcome-only supervision, by contrast, rewards a whole trajectory whenever its final answer is correct, even if that answer came from parametric memory rather than retrieved evidence.

On top of this formulation, RAG-Gym decomposes the design of search agents into three dimensions: architecture design, parameter optimization, and action evaluation. For each dimension, we compare a set of candidate strategies and combine the best-performing choices into a single agent, Re²Search++. With Llama-3.1-8B, Re²Search++ improves the F1 score on HotpotQA from 41.1% (ReAct) to 60.2%.

RAG-Gym framework

🏋️ Dimension 1: Architecture Design

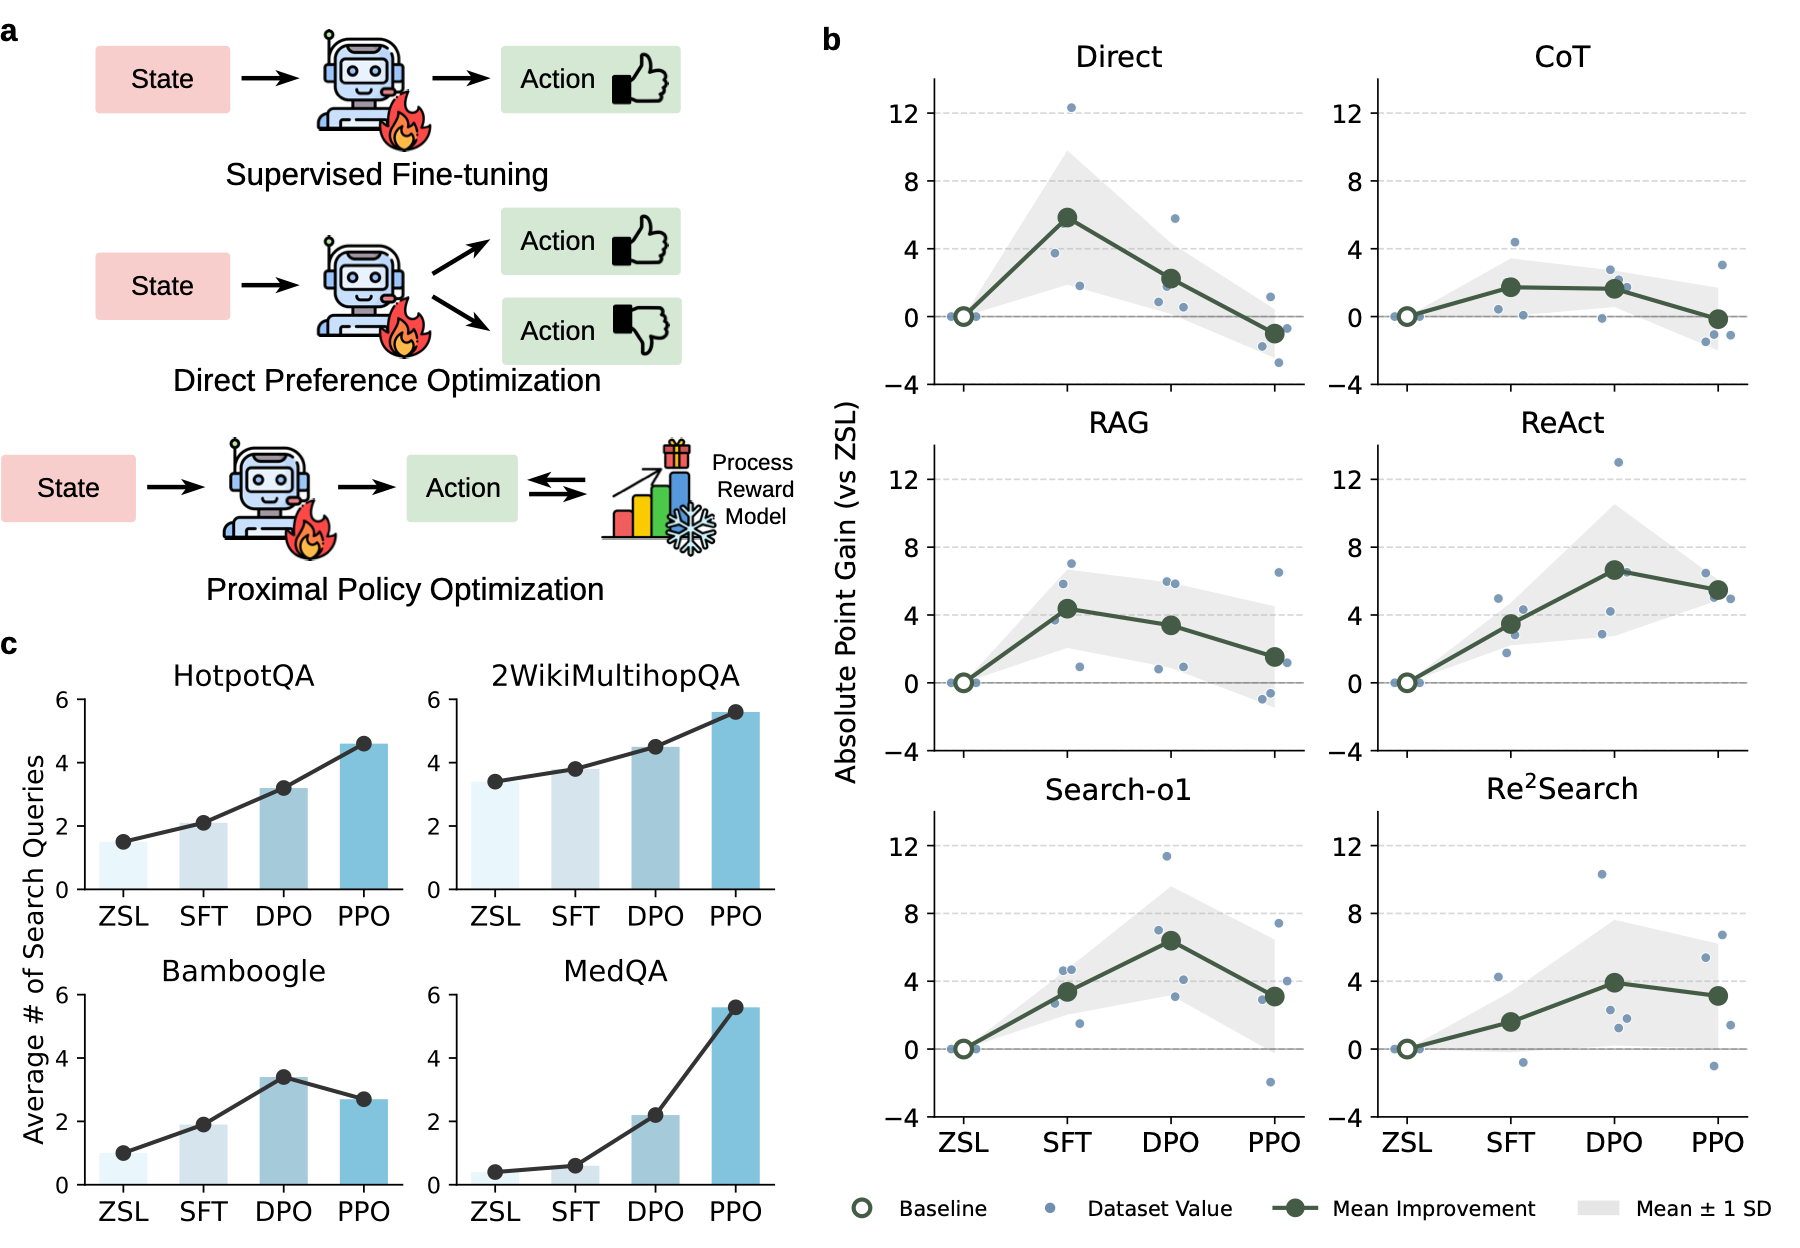
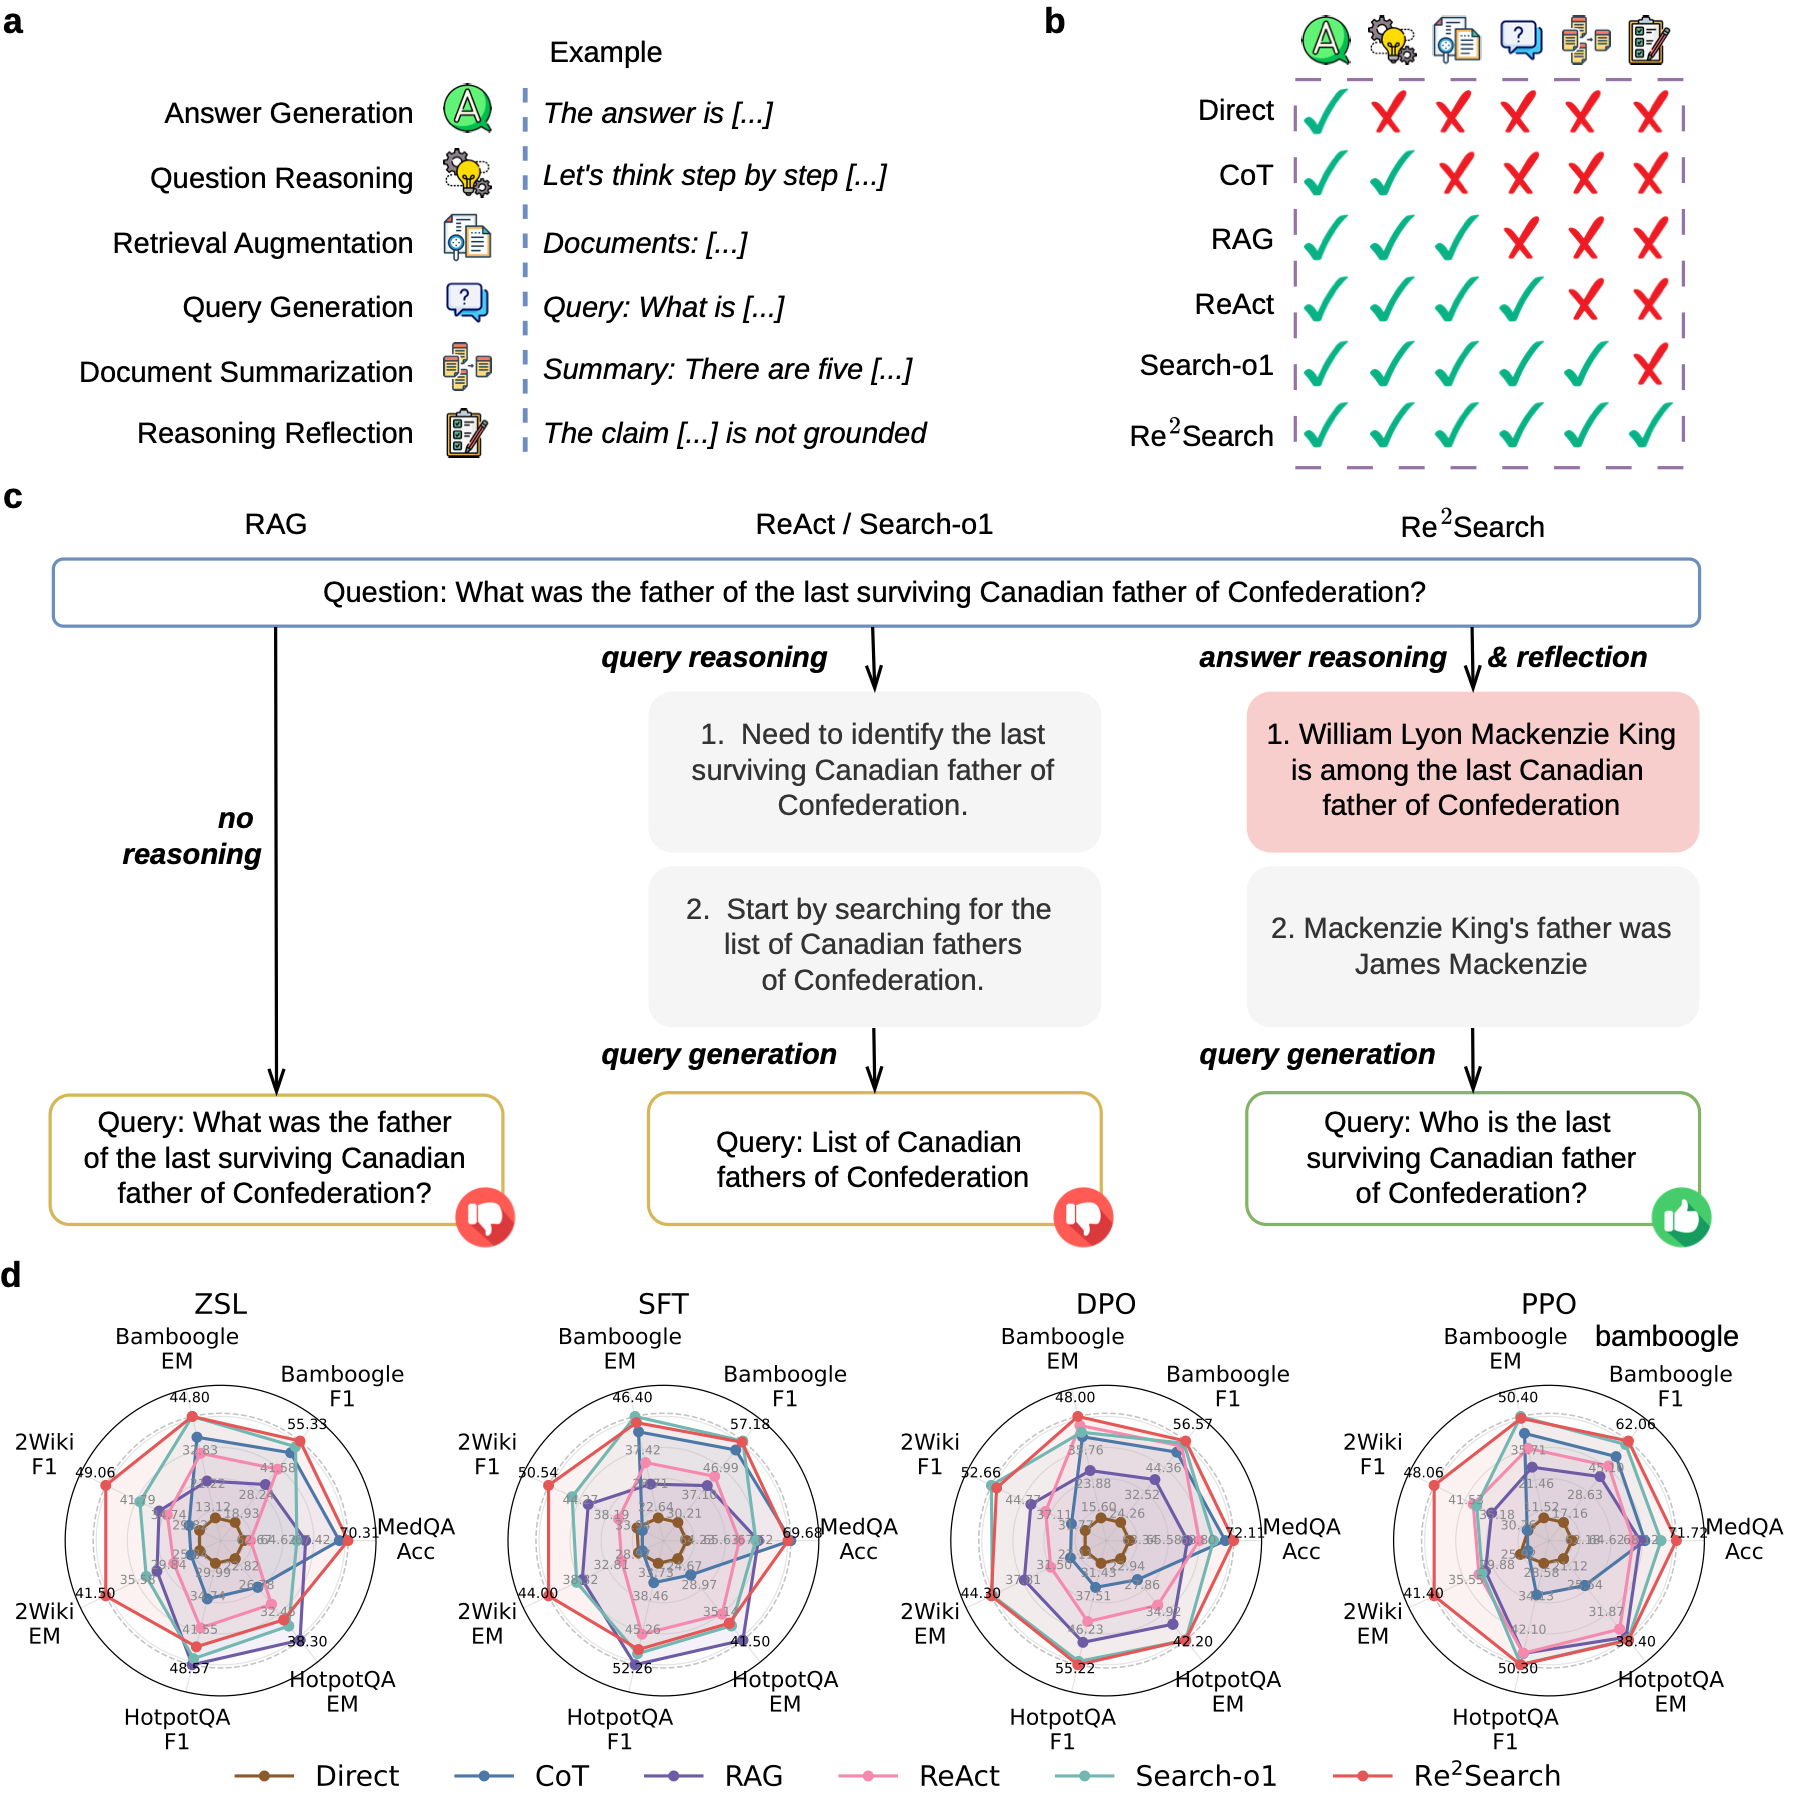
We decompose the capabilities of search agents into six functional modules: answer generation, question reasoning, retrieval augmentation, query generation, document summarization, and reasoning reflection. Existing architectures, from Direct prompting and CoT to RAG, ReAct, and Search-o1, each add one capability to the previous design, but none checks whether its reasoning is supported by evidence before searching. RAG-Gym introduces a new agent architecture called Re²Search (Reasoning, Reflection, and Search) that adds this step. At each step, the agent will:

  1. Draft a reasoning chain and a tentative answer from the information gathered so far.
  2. Reflect on the reasoning chain to find claims that are not yet supported by retrieved evidence.
  3. Turn the first unsupported claim into a targeted search query.

Reflection is built into the architecture and needs no reflection-specific training or ground-truth answer. Re²Search is the only architecture that includes all six modules.

Agent architectures

Across the four benchmarks, Re²Search consistently achieves the highest performance among the six architectures, and the advantage persists under zero-shot learning (ZSL) and after SFT, DPO, or PPO training. In the example above, ReAct and Search-o1 search for a generic list of Canadian fathers of Confederation, while Re²Search first verifies the specific claim its answer depends on.

💪 Dimension 2: Parameter Optimization

RAG-Gym tunes the actor (the LLM itself) with fine-grained process supervision, giving feedback on each intermediate action rather than only the final answer. We compare zero-shot learning (ZSL) with three post-training algorithms: supervised fine-tuning (SFT), direct preference optimization (DPO), and proximal policy optimization (PPO).

Process supervision consistently improves over zero-shot baselines, but the best algorithm depends on the agent. Single-step agents (Direct, CoT, and RAG) reach their peak with SFT. Multi-step agents (ReAct, Search-o1, and Re²Search) benefit substantially more from DPO and PPO, whose negative signals teach the agent which search actions to avoid. DPO gives Re²Search its largest improvement, increasing F1 scores by an average of 3.92% over the zero-shot baseline. Process-supervised agents also issue more search queries at inference than their zero-shot counterparts, a sign that they have learned to recognize the limits of their own knowledge.

Parameter optimization

🧐 Dimension 3: Action Evaluation

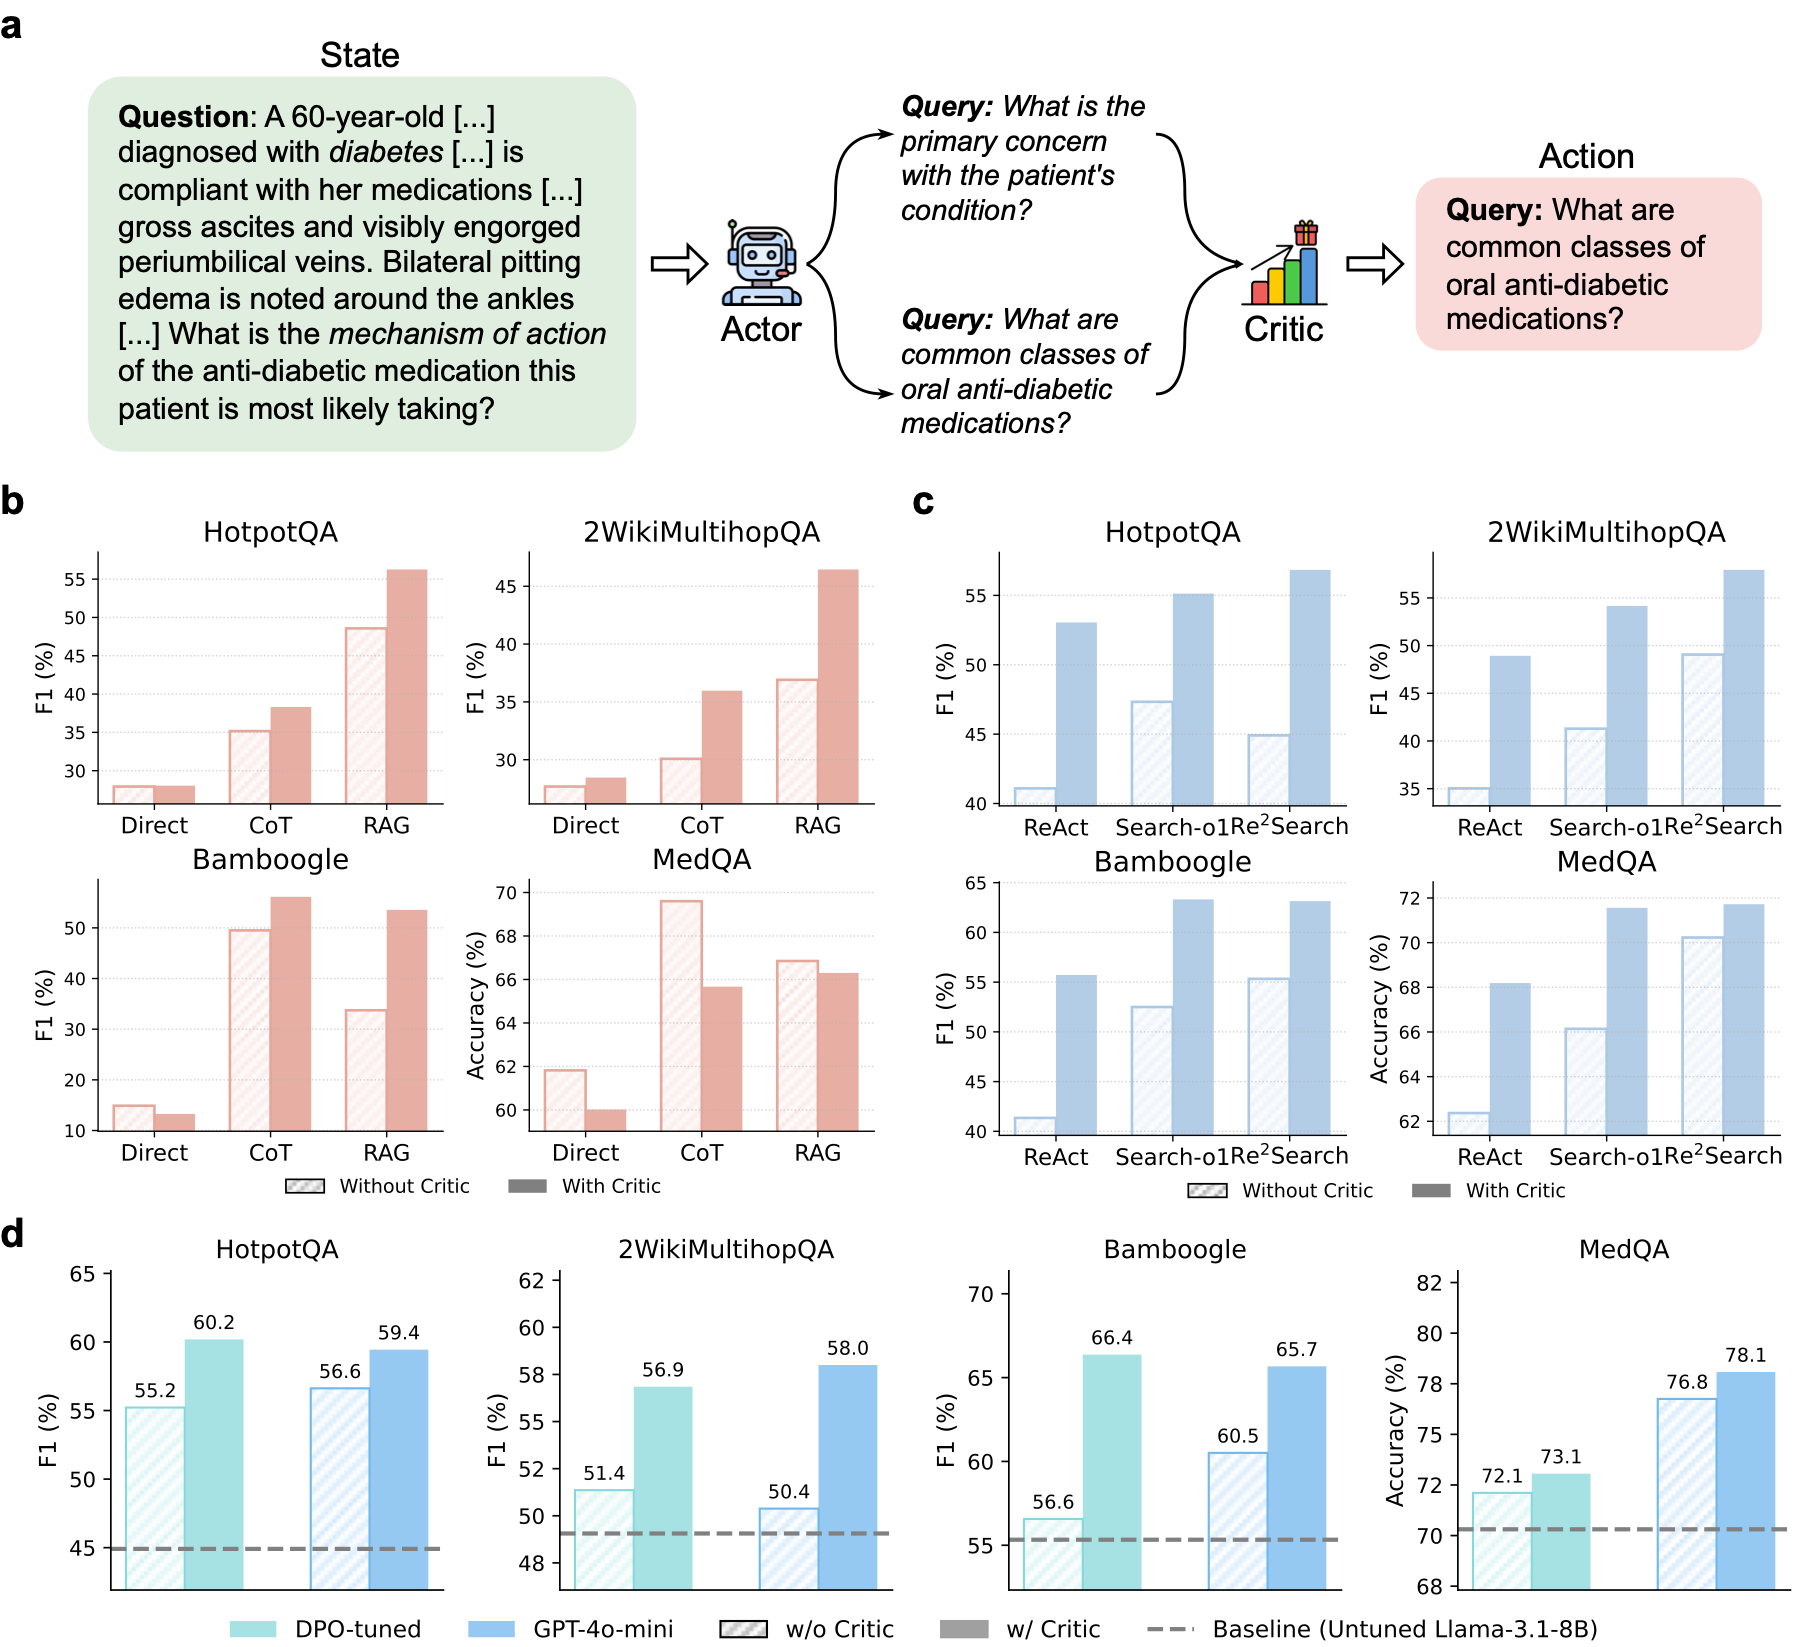
Beyond optimizing the actor, RAG-Gym trains a critic, an external reward model that scores the actions an agent proposes. During inference, the actor generates multiple candidate actions for the current state, the critic scores them, and the agent executes the highest-scoring one (Best-of-N). This mechanism offers two key advantages:

  • Better multi-step search: Critic guidance improves CoT, RAG, ReAct, Search-o1, and Re²Search on the general-domain benchmarks. On MedQA, only the multi-step agents (ReAct, Search-o1, and Re²Search) gain substantially, suggesting that the critic mainly helps agents navigate sequential retrieval rather than check final answers.
  • Transfer across models: A critic trained only on Llama-3.1-8B trajectories improves both a DPO-tuned Llama-3.1-8B actor and GPT-4o-mini, raising GPT-4o-mini's MedQA accuracy from 76.8% to 78.1%. Lightweight open-source critics can therefore guide proprietary models without access to their weights.
Action evaluation

🏆 Re²Search++: Process Supervision Generalizes Better

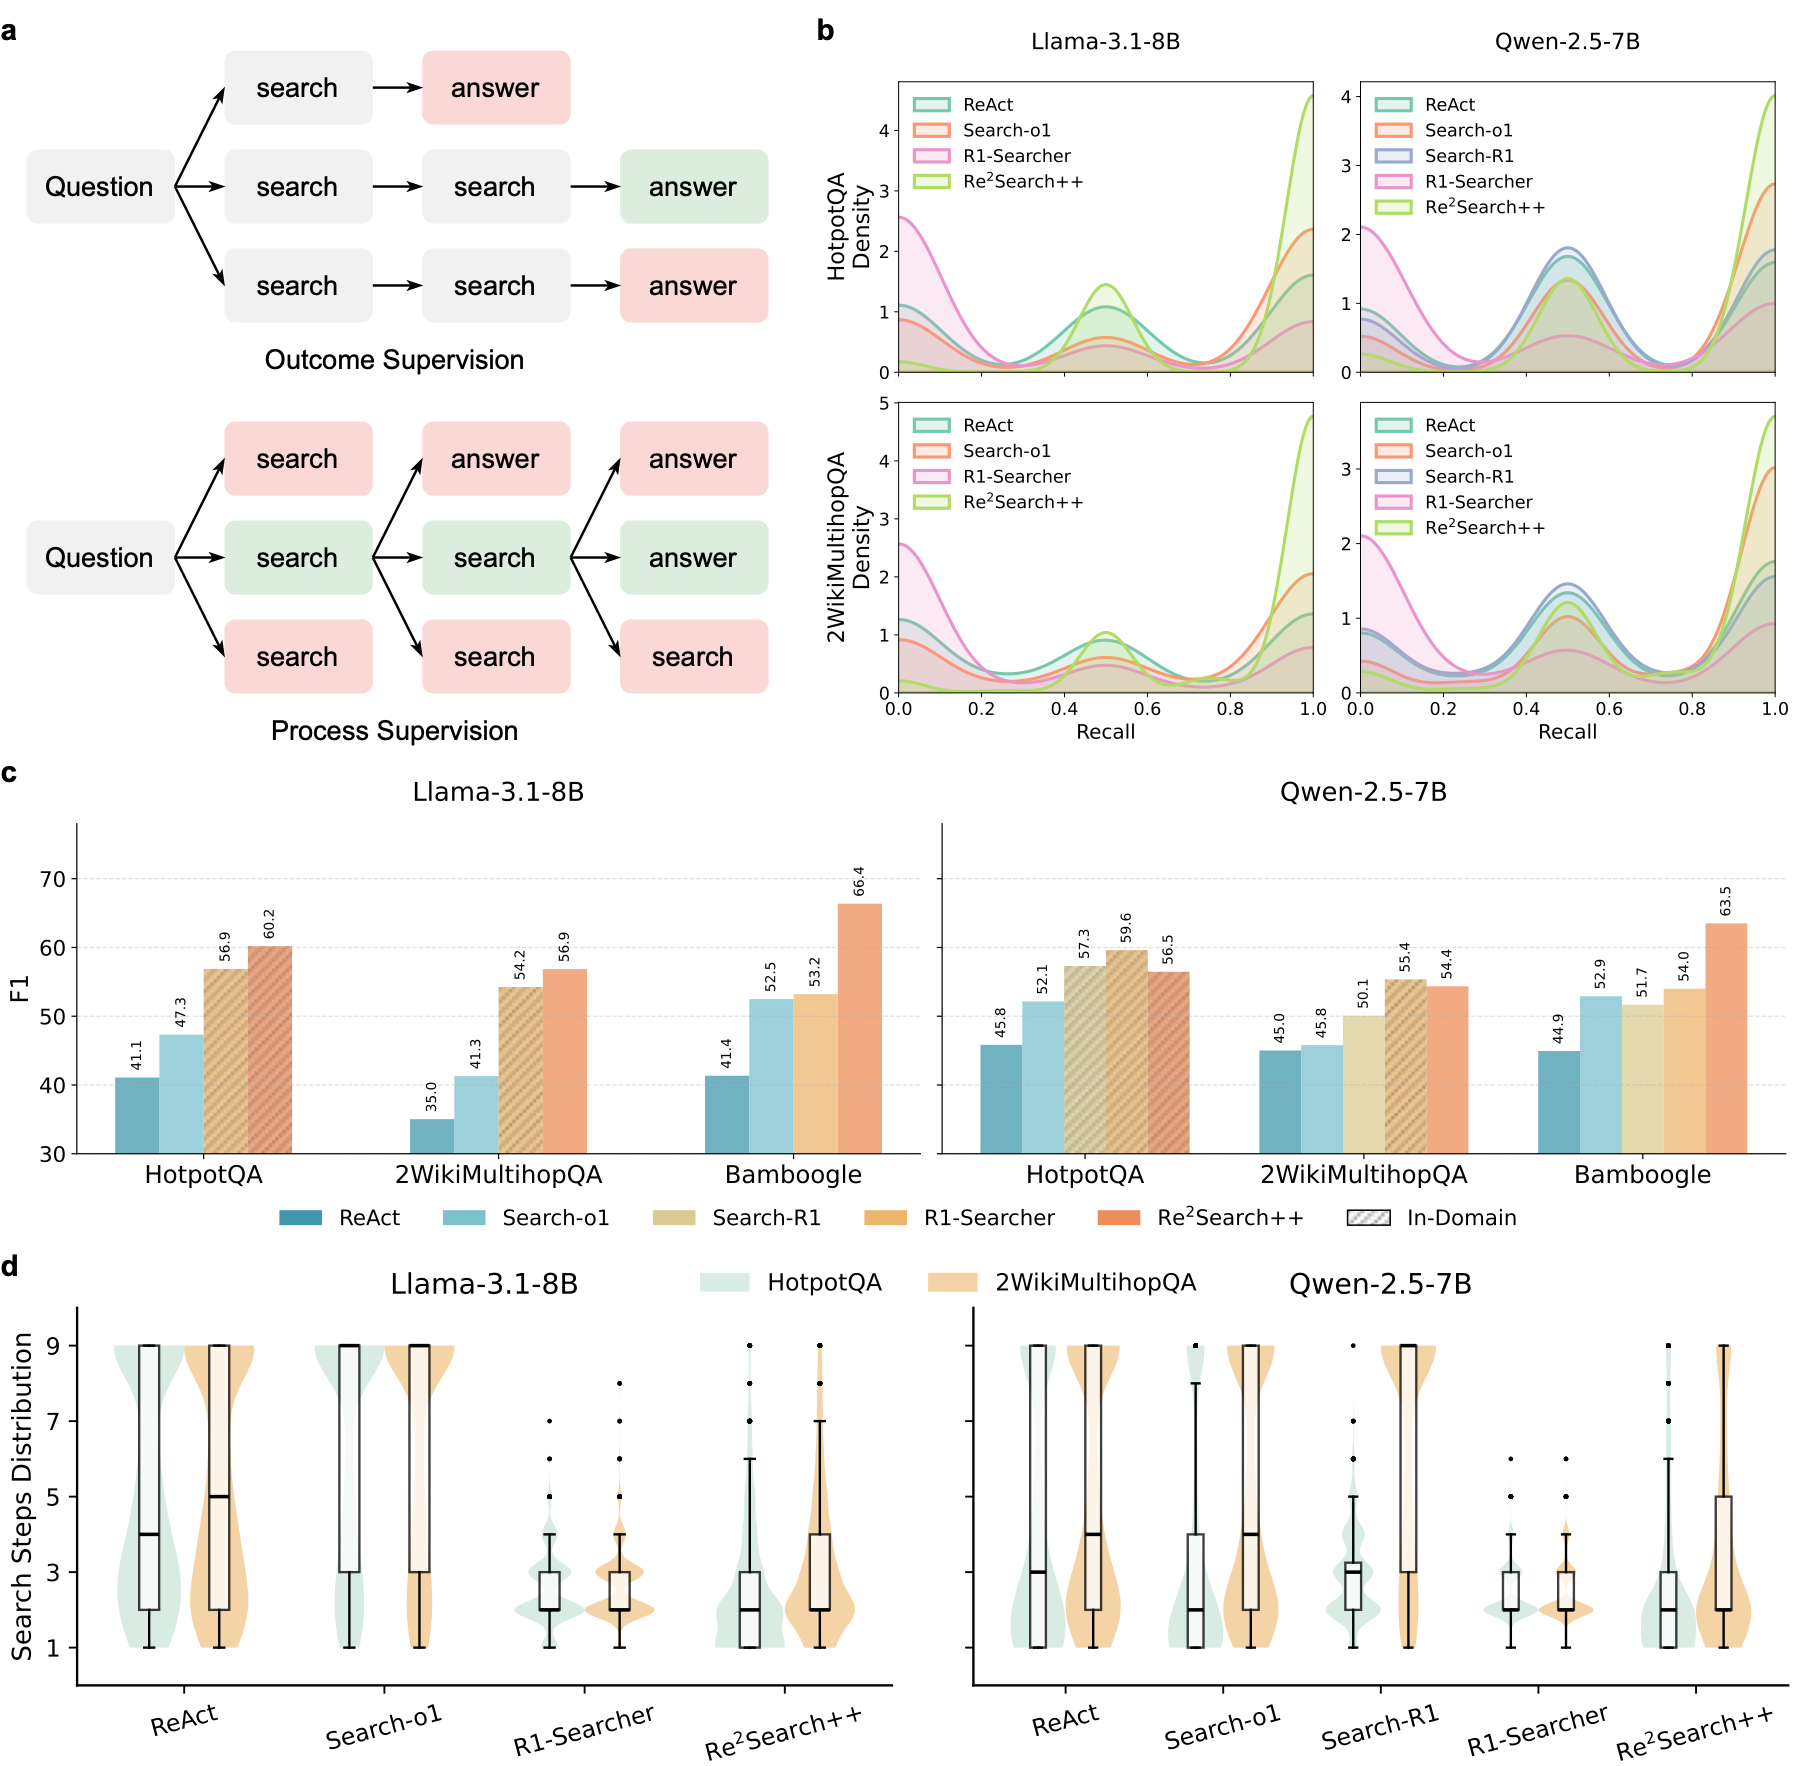
Re²Search++ combines the best choice from each dimension: the Re²Search architecture, DPO training, and critic-guided inference. We compare it with strong outcome-supervised agents, Search-R1 and R1-Searcher, which reinforce trajectories based only on the correctness of the final answer. Outcome supervision works well in domain, but these agents degrade on out-of-domain datasets. Re²Search++, tuned on HotpotQA, remains comparable or better on their in-domain tasks and generalizes better to unseen benchmarks, most clearly Bamboogle (66.4% vs. 53.2% F1 for R1-Searcher with Llama-3.1-8B).

Retrieval recall shows why. Outcome-supervised agents often reach correct answers with low recall of the ground-truth documents, suggesting reliance on parametric memory rather than retrieved evidence. Re²Search++ recalls the highest fraction of ground-truth documents with both Llama-3.1-8B and Qwen-2.5-7B (85.5% vs. 27.5% for R1-Searcher on HotpotQA with Llama-3.1-8B), while issuing comparable or fewer search queries.

Process vs. outcome supervision

Analysis and Discussion

Quality of Process Supervision Signals

The value of process supervision depends on where the reward comes from. We compare an outcome reward model (ORM) with process reward models (PRMs) trained on random preferences, Monte Carlo rollouts, or annotations from Llama-3.1-8B or GPT-4o. Rollout-based rewards, widely used for mathematical reasoning, perform poorly for retrieval: on 2WikiMultihopQA, the rollout PRM reaches 49.57% F1, below the ORM at 55.59%. A correct final answer can come from parametric memory even when the search trajectory is irrelevant, so rollouts end up reinforcing flawed trajectories. As the table below shows, GPT-4o annotations produce the best critic on all four datasets. They also agree most with human judgment, reaching 85.85% agreement with medical experts on MedQA, and human annotators endorsed GPT-4o's top-ranked action in 82% of 100 sampled HotpotQA steps.

Type Outcome Source Process Source HotpotQA
(EM / F1)
2WikiMultihopQA
(EM / F1)
Bamboogle
(EM / F1)
MedQA
(Acc / Agree)
ORM Truth -- 41.10 / 53.35 47.70 / 55.59 43.20 / 57.46 66.77 / --
PRM (Random) -- -- 32.20 / 42.83 35.70 / 42.00 38.40 / 47.86 68.26 / 50.00
PRM (Rollout) Truth Rollout 39.60 / 51.85 42.94 / 49.57 48.80 / 56.05 68.34 / 71.03
PRM (Llama) Truth Llama-3.1-8B 40.30 / 51.74 40.70 / 48.22 44.80 / 54.36 68.50 / 65.99
PRM (GPT) Truth GPT-4o 44.10 / 56.84 50.20 / 57.94 51.20 / 63.15 71.96 / 85.85

Training Data Scaling

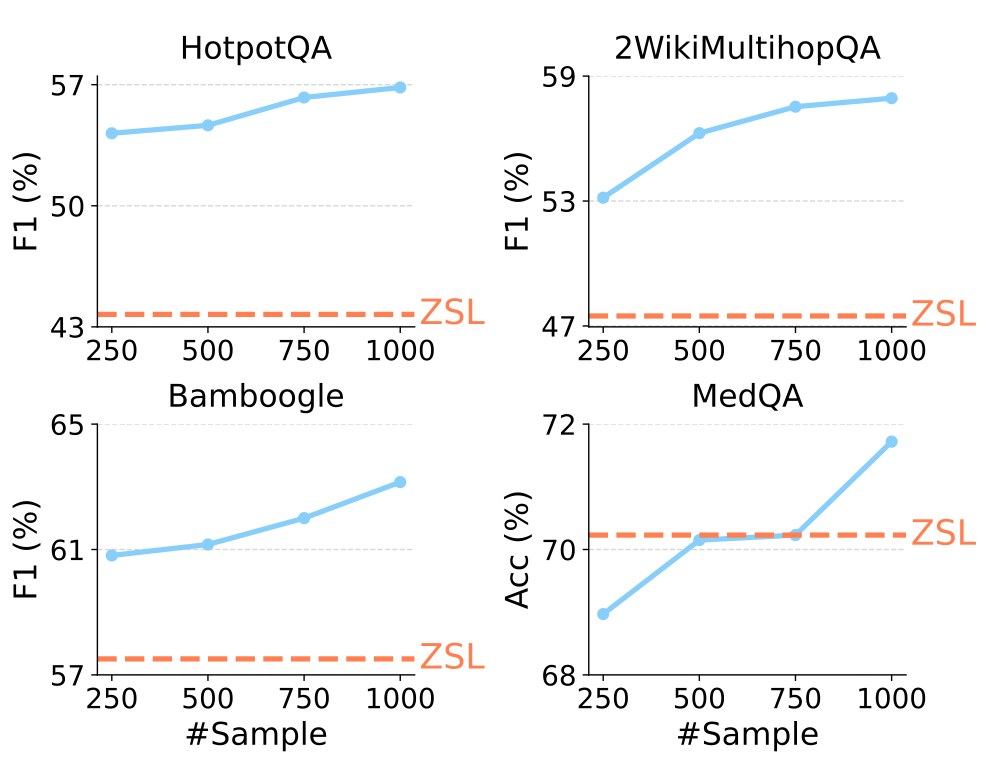
We vary the number of process-reward samples used to train the critic from 250 to 1,000. On HotpotQA, 2WikiMultihopQA, and Bamboogle, as few as 250 samples already yield substantial F1 gains over the zero-shot (ZSL) baseline. MedQA needs more data: accuracy starts below the baseline at 250 samples and peaks at 1,000, suggesting that domain-specific reasoning takes longer to learn.

Training data scaling

Inference Compute Scaling

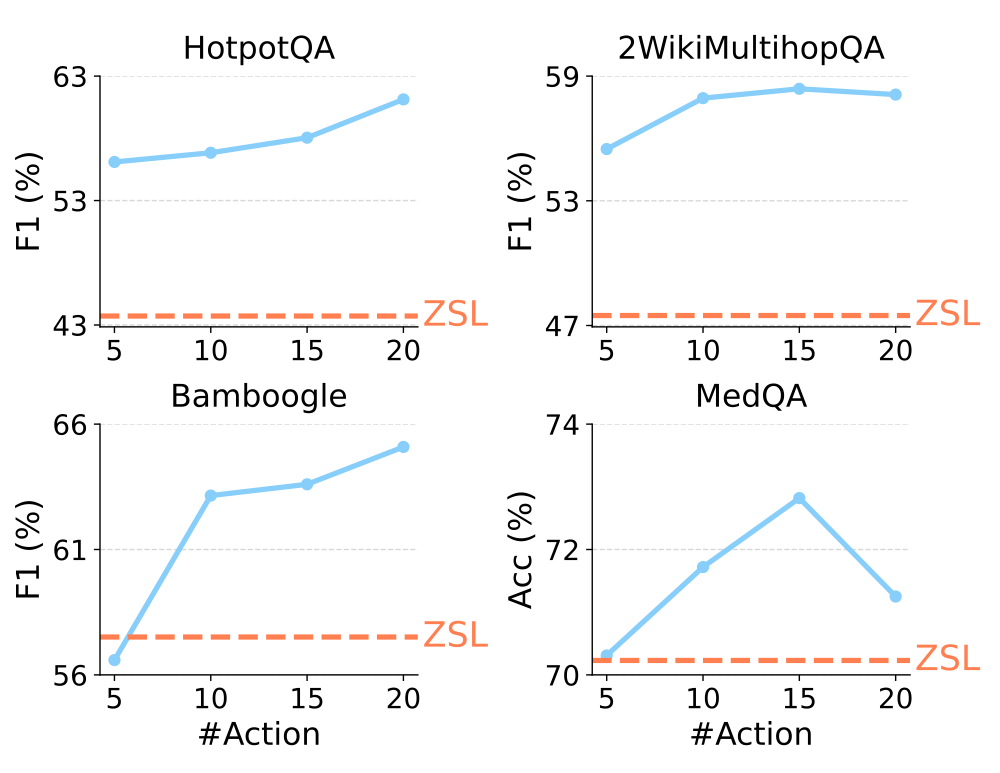
Sampling more candidate actions at each step improves performance up to a saturation point, typically between N = 15 and N = 20. Beyond that, returns diminish, and on MedQA accuracy drops from 72.8% at N = 15 to 71.2% at N = 20, likely because a larger pool raises the chance of flawed actions that still score highly. A moderate budget of N around 10 to 15 offers the best balance between accuracy and cost.

Inference compute scaling

BibTeX

@article{xiong2026supervising,
  title={Supervising the search process produces reliable and generalizable information-seeking agents},
  author={Guangzhi Xiong and Qiao Jin and Xiao Wang and Yin Fang and Haolin Liu and Yifan Yang and Fangyuan Chen and Zhixing Song and Dengyu Wang and Minjia Zhang and Zhiyong Lu and Aidong Zhang},
  journal={Nature Communications},
  year={2026},
  doi={10.1038/s41467-026-78807-z},
  url={https://www.nature.com/articles/s41467-026-78807-z}
}